
模型在 notebook 裡成功算出一次預測,另一個程式仍然不知道該怎麼使用它。對方可能沒有標準化資料,也不知道四個數字的順序;即使拿到一個 .8,也不知道這代表哪個類別,或這次回應來自哪一版模型。
把模型變成服務,第一個要完成的工作,是讓一次預測有清楚的輸入、固定的計算方式與可辨認的輸出。API 是這個邊界;Pipeline 則把邊界後面的前處理與模型接在一起。
本篇用四特徵的合成分類資料,真正訓練、保存、載入模型,再啟動本機 HTTP 服務。你可以重跑成功請求與錯誤請求,確認伺服器實際做了什麼。這些操作回答的是「訓練後怎麼穩定交給另一個程式呼叫」,不是已完成對外部署或取得真實業務成效。
先決定合約,再決定 endpoint 長什麼樣
先想像呼叫端是一個不知道模型內部細節的資料處理程式。它需要把一批資料送進來,收到每筆分類與 class 1 的機率。雙方至少要同意:
這裡的四欄是人工特徵名稱,沒有借用某種業務定義。數值依位置輸入,順序必須跟 metadata 一致。四個值若都合法、卻把 a 與 b 對調,格式驗證無法知道;實務上仍需欄位映射、單位與資料來源的治理。
API 合約不等於模型已理解資料語意。它能擋下三欄、五欄或字串,不能只看四個數字就判斷它們是否量到正確的現象。
訓練與服務,為什麼要共用一份 Pipeline?
標準化的計算很短,卻容易在兩個地方各寫一遍。訓練時用一組平均與尺度,API 卻拿整批 request 重新計算,預測就不再是原本訓練的那個函數。只保存 LogisticRegression 係數、漏掉 scaler,也會造成同樣問題。
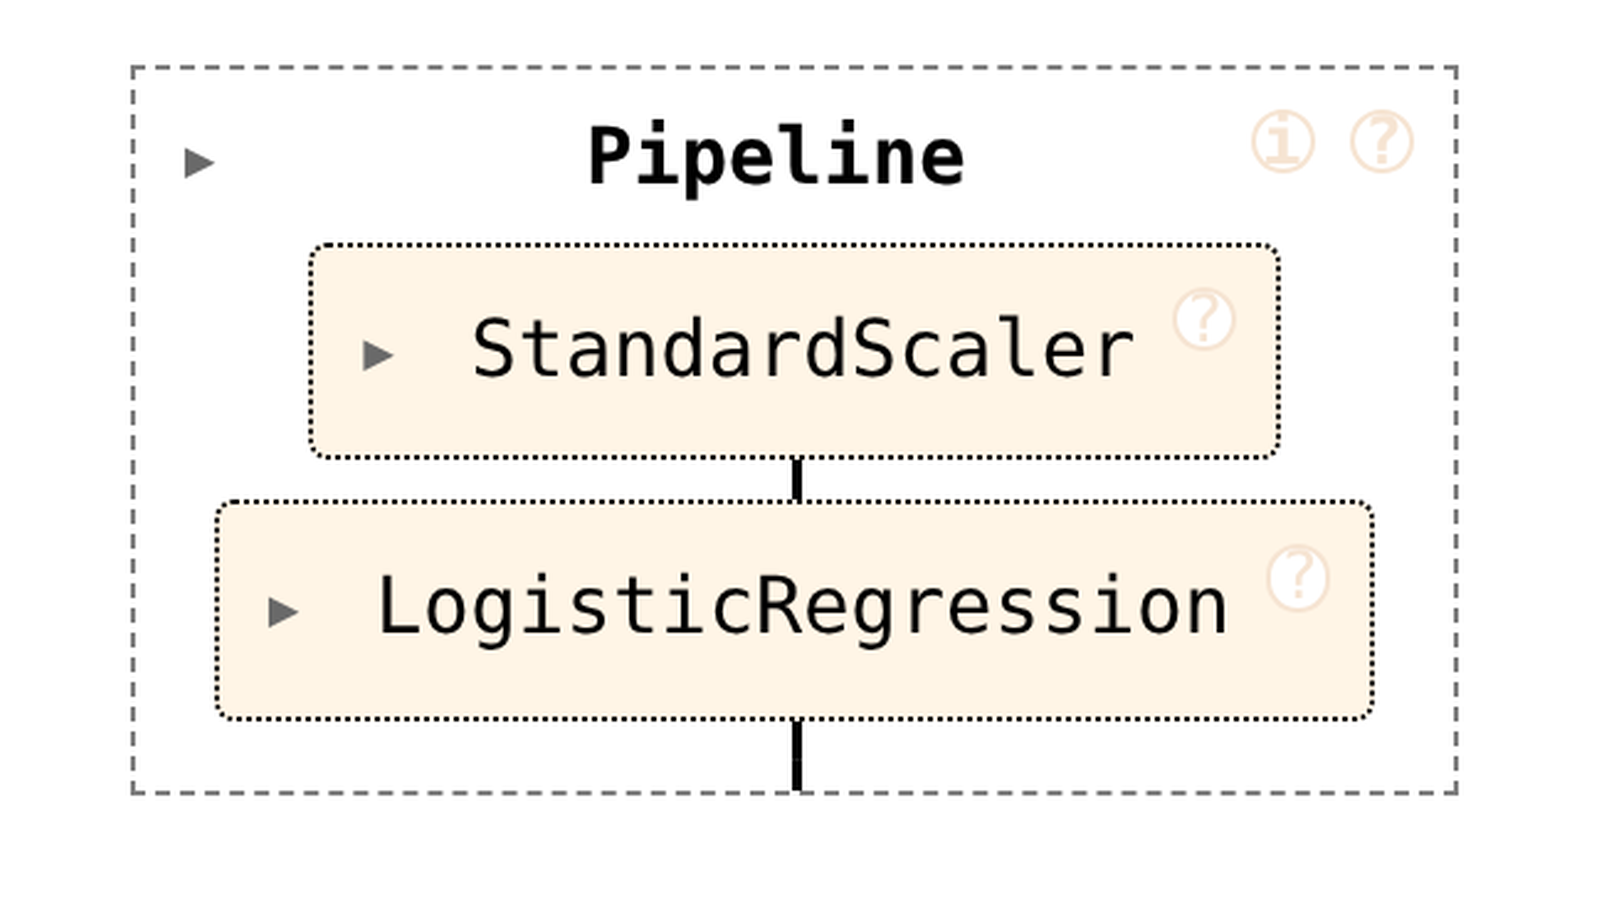
本例把兩個步驟放進同一個 sklearn Pipeline:
原始四欄 → 已 fit 的 StandardScaler → 已 fit 的 LogisticRegression
先固定分割 240 筆合成資料,180 筆 train、60 筆 test;接著只對 train 呼叫 Pipeline.fit。這會用 train fit scaler,再把轉換後的 train 交給分類器。test 只走已有參數的轉換與預測,不參與平均、尺度或係數估計。
服務載入的是整份已 fit Pipeline。每個 request 只呼叫 predict 與 predict_proba,不對當次 batch 重新 fit。單筆與批次請求都應該使用相同的前處理參數;不能因為一次送了不同的鄰居資料,就偷偷換一個 scaler。
用二元 LogisticRegression 展開一次預測,可以檢查這個約定:
z_j = (x_j − train_mean_j) / train_scale_j
logit = Σ_j coefficient_j × z_j + intercept
p(class 1) = 1 / (1 + exp(−logit))
這份式子使用的是模型已保存的參數,而不是 request 自己的統計量。本次 client 對所有正常測例另寫這段運算,與 HTTP 回傳機率的最大差為 0。這支持前處理與輸出的機械一致性,沒有證明模型已校準,或資料分布不會改變。
Artifact 不只是一個檔名:把版本與資料順序帶著走
訓練程式保存三個本機檔案:Pipeline 的 joblib、metadata,以及供 client 使用的三列測試 fixture。metadata 記錄特徵順序、類別說明、模型版本、實際套件版本、資料與分割設定、artifact SHA256,以及可核對的已 fit 參數。
啟動 API 時,程式先檢查 metadata 的版本、特徵順序與預期模型版本,核對檔案 digest,然後載入 Pipeline 一次。載入完成後才回報 ready。每次預測回傳同一個模型版本,呼叫端才有辦法辨認結果來自哪個模型。
這裡有兩個不能混在一起的判斷。Digest 相符表示檔案跟本機 metadata 一致,不表示來源可信;joblib 依賴 pickle 類型機制,載入不可信檔案可能執行程式。本例只載入自己剛訓練的固定本機路徑,不提供上傳任意模型的 endpoint。
相同的版本紀錄也只是此範例的相容性檢查,不是對所有平台、依賴或未記錄套件的完整保證。本文實際訓練與服務使用同一個既有環境,沒有宣稱拿到任意 joblib 都能跨版本使用。
用 HTTP 傳什麼,收到的機率又代表什麼?
服務只開在本機 127.0.0.1:8769。GET /health 在成功載入後回 ready、特徵順序、模型版本與載入次數。它回答這個範例是否已載入模型,不涵蓋身分驗證、所有外部依賴或正式環境健康。
POST /predict 接受以下形狀。這裡用容易閱讀的手設數值示範格式;完整驗證程式會另外送出保存的 held-out fixture。
{"rows": [[0, 1, -2, 3]]}
保存的 fixture 第一筆實際回應是:
{"model_version":"synthetic-four-feature-v1","positive_class":1,"predictions":[{"class":1,"probability_class_1":0.7971203905962692}]}
最後的數字一直是 class 1 的機率分量,不能因為預測 class 改變,就讀成「預測類別的信心」。三筆 fixture 的實際結果可看出差別:
| fixture 位置 | 預測 class | class 1 機率,約值 |
|---|---|---|
| 1 | 1 | .7971203906 |
| 2 | 1 | .9133072217 |
| 3 | 0 | .06610275134 |
第三列預測 class 0,回傳的 .0661 仍然是 class 1 的值,不是說 class 0 只有 6.61% 信心。欄位名稱與 positive_class 明確寫出這個語意,比只回一個含糊的 score 更有用。
FastAPI 依輸入模型產生的 OpenAPI,能讓 Swagger UI 呈現 request schema 與操作介面,但不能只看見文件頁,就以為輸出也已驗證。本例沒有宣告 response_model;保存的 OpenAPI 中 200 response schema 是空物件。上圖的 JSON 是實際 response,並不是框架已按輸出模型檢驗的證據;本篇另外用 client 比對輸出值。
機率落在 0 到 1 之間,也不代表已經過校準。本文沒有做校準實驗;原合成 test 的 accuracy=.9、log loss 約 .29056645775,只是固定設定與一次分割的結果,不是 API 正確性的替代品,更不是真實業務品質。
驗證不只看 shape:拒絕字串、bool 與無法序列化的錯誤
普通 float 欄位可能幫忙轉型。若約定輸入必須是真正數值,不能只寫 float,就以為字串 "1.0" 已被擋下。
本例在 Pydantic 2 使用 strict float、禁止非有限值,並分別限制外層筆數、每列四欄與額外欄位。JSON 整數與浮點都可接受;數字字串、bool、null、空 batch 與多餘欄位均拒絕。
還有一個藏在錯誤回應裡的問題。NaN 與 Infinity 並非標準 JSON 數值,但目前解析器可能先接成 Python 非有限值,再由 validation 拒絕。若錯誤處理器把原 input 原封不動放進 JSONResponse,回應自己就可能因 NaN/Infinity 而無法序列化,讓應該是輸入錯誤的案例變成 500。
因此這裡自訂 RequestValidationError handler,只回傳 type、loc 與 msg,不回 input 與 ctx。實際送入 raw NaN 的回應為 HTTP 422:
{"detail":[{"type":"finite_number","loc":["body","rows",0,0],"msg":"Input should be a finite number"}]}
loc 指出第一列第一欄。raw Infinity、負 Infinity、1e400 與破損 JSON 也實際得到 422 JSON;不是只在函式裡建立幾個 Python 物件做驗證。
有限還不等於一定算得出來。1e308 本身是有限浮點數,卻可能在標準化或點積時溢位。本例另外捕捉模型計算的數值範圍錯誤,回 422 numerical_range,沒有把失敗偽裝成正常機率。這個測例不代表已證明所有有限輸入的穩定性,只清楚分開了格式合法與目前模型能否運算。
怎麼確認服務真的載入一次,而不是每個 request 重訓?
驗證程式先訓練自己的 artifact,再建立 uvicorn 子程序,等 /health ready 後透過 HTTPX 發出請求。結束時再讀一次 health,並比較前後 artifact digest。
本次保存的 22 個回應包含:
| 類型 | 回應數 | 實際結果 |
|---|---|---|
| 前後 health、單筆、三筆 batch、整數輸入、32 筆 batch | 6 | 200 |
| 空 batch、33 筆、欄數錯、字串、bool、null、extra、缺欄、非矩陣、過大有限值 | 11 | 422 |
| raw NaN/Infinity/負 Infinity、1e400、破損 JSON | 5 | 422 |
前後載入次數維持 1,artifact digest 未改;程式的 request 路徑只有 predict 與 predict_proba,沒有 fit。完整 stdout 保存每個 request 的 status 與 JSON body,正常請求還核對 Pipeline 與手寫標準化/點積/sigmoid。
這些檢查各自回答不同問題。回 200 不證明輸出對;比對數值不證明錯誤處理可靠;檔案未改也不能單獨證明程式未在記憶體偷偷重訓。要把路徑、輸出與生命週期一起檢查,才知道服務是否符合這份合約。
服務程序只綁 loopback。port 8769 已被占用時,驗證程式會停止,不搜尋或終止其他程序。finally 只回收本次建立的 Popen;本次保存 exit code −15,表示送出 SIGTERM 並回收自己的 child,不是已驗證完整 production shutdown、並發或負載能力。
完整可執行程式:訓練、服務與 client 放在同一個目錄
以下三個檔案與 requirements 存在同一個 practice 目錄。實跑環境為 Python 3.10.12,FastAPI .128.7、Pydantic 2.12.5、sklearn 1.5.1、numpy 1.26.3,其餘版本列於下面。原型已在此既有環境實際啟動 HTTP 並檢查回應;沒有重新安裝依賴或驗證另一個平台的新環境。
若已有對應環境,在 WSL 進入這些檔案所在目錄後執行:
python3 verify_http.py > stdout.json
若要另建環境,可以依 requirements 安裝後再執行;這是可供重現的順序,不是本次已驗證新環境安裝成功的紀錄:
python3 -m venv .venv
. .venv/bin/activate
python -m pip install -r requirements.txt
python verify_http.py > stdout.json
驗證程式會自行依序訓練、啟動服務、發出 HTTP 與回收程序,不必先另外啟動一個 uvicorn。成功時 exit 0,stdout 可解析成 JSON,22 筆回應符合前表,manual probability 最大差為 0、artifact unchanged 為 true、最後 load count 為 1。失敗時先看 traceback 與同目錄的 server-run.log,不要把舊 stdout 當本次成功。
requirements.txt:
numpy==1.26.3
scipy==1.14.0
scikit-learn==1.5.1
joblib==1.4.2
threadpoolctl==3.5.0
fastapi==0.128.7
pydantic==2.12.5
uvicorn==0.41.0
httpx==0.28.1
train_model.py:
"""Original synthetic train-only Pipeline; writes only this demo's own trusted artifact."""
import hashlib
import json
import platform
from pathlib import Path

import fastapi
import httpx
import joblib
import numpy as np
import pydantic
import sklearn
import uvicorn
from sklearn.datasets import make_classification
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import accuracy_score, log_loss
from sklearn.model_selection import train_test_split
from sklearn.pipeline import Pipeline
from sklearn.preprocessing import StandardScaler

BASE = Path(__file__).resolve().parent
ARTIFACTS = BASE / "artifacts"
FEATURE_ORDER = ["signal_a", "signal_b", "signal_c", "signal_d"]
MODEL_VERSION = "synthetic-four-feature-v1"


def runtime_versions():
    return {"python": platform.python_version(), "numpy": np.__version__,
        "scikit_learn": sklearn.__version__, "joblib": joblib.__version__,
        "fastapi": fastapi.__version__, "pydantic": pydantic.__version__,
        "uvicorn": uvicorn.__version__, "httpx": httpx.__version__}


def train():
    x, y = make_classification(n_samples=240, n_features=4, n_informative=3,
        n_redundant=0, n_clusters_per_class=1, flip_y=.04, random_state=42)
    train_ids, test_ids = train_test_split(np.arange(len(y)), test_size=.25,
        stratify=y, random_state=17)
    pipeline = Pipeline([("scale", StandardScaler()),
        ("classifier", LogisticRegression(max_iter=1000, random_state=0))])
    pipeline.fit(x[train_ids], y[train_ids])  # No test fit or refit after evaluation.
    probability = pipeline.predict_proba(x[test_ids])
    prediction = pipeline.predict(x[test_ids])
    ARTIFACTS.mkdir(exist_ok=True)
    model_path = ARTIFACTS / "pipeline.joblib"
    joblib.dump(pipeline, model_path, compress=0, protocol=5)
    metadata = {"model_version": MODEL_VERSION, "feature_order": FEATURE_ORDER,
        "label_map": {"0": "synthetic_negative", "1": "synthetic_positive"},
        "probability_semantics": "probability_class_1 is model predict_proba for class1, not calibrated assurance",
        "classes": pipeline.classes_.tolist(), "runtime_versions": runtime_versions(),
        "artifact_sha256": hashlib.sha256(model_path.read_bytes()).hexdigest(),
        "training_recipe": {"n_samples": 240, "data_seed": 42, "split_seed": 17,
            "train_count": len(train_ids), "test_count": len(test_ids),
            "scaler_fit_scope": "180trainingrows only; population variance, no testfit",
            "pipeline": "StandardScaler -> LogisticRegression(max_iter1000,random_state0)",
            "train_ids": train_ids.tolist(), "test_ids": test_ids.tolist()},
        "heldout_toy_metrics": {"accuracy": float(accuracy_score(y[test_ids], prediction)),
            "log_loss": float(log_loss(y[test_ids], probability, labels=pipeline.classes_))},
        "fitted_values_for_checking": {"scaler_mean": pipeline.named_steps["scale"].mean_.tolist(),
            "scaler_scale": pipeline.named_steps["scale"].scale_.tolist(),
            "classifier_coef": pipeline.named_steps["classifier"].coef_.tolist(),
            "classifier_intercept": pipeline.named_steps["classifier"].intercept_.tolist()},
        "limits": "Handset recipe and one fixed random split; no CV/tuning/real-world accuracy claim"}
    (ARTIFACTS / "metadata.json").write_text(json.dumps(metadata, indent=2) + "\n")
    fixture = {"rows": x[test_ids[:3]].tolist(), "labels": y[test_ids[:3]].tolist()}
    (ARTIFACTS / "client_fixture.json").write_text(json.dumps(fixture, indent=2) + "\n")
    return metadata


if __name__ == "__main__":
    print(json.dumps(train(), indent=2))
api_app.py:
"""Loopback teaching API; loads the locally trained trusted artifact once, never fits."""
import hashlib
import json
from contextlib import asynccontextmanager
from typing import Annotated

import joblib
import numpy as np
from fastapi import FastAPI, HTTPException, Request
from fastapi.exceptions import RequestValidationError
from fastapi.responses import JSONResponse
from pydantic import BaseModel, ConfigDict, Field

from train_model import ARTIFACTS, FEATURE_ORDER, MODEL_VERSION, runtime_versions

Number = Annotated[float, Field(strict=True, allow_inf_nan=False)]
Row = Annotated[list[Number], Field(min_length=4, max_length=4)]


class PredictInput(BaseModel):
    model_config = ConfigDict(extra="forbid")
    rows: Annotated[list[Row], Field(min_length=1, max_length=32)]


@asynccontextmanager
async def lifespan(app):
    metadata = json.loads((ARTIFACTS / "metadata.json").read_text())
    if metadata["runtime_versions"] != runtime_versions():
        raise RuntimeError("Use the recorded training environment for this own artifact")
    if metadata["feature_order"] != FEATURE_ORDER or metadata["model_version"] != MODEL_VERSION:
        raise RuntimeError("Artifact schema/version does not match this demo API")
    path = ARTIFACTS / "pipeline.joblib"
    digest = hashlib.sha256(path.read_bytes()).hexdigest()
    if digest != metadata["artifact_sha256"]:
        raise RuntimeError("Local artifact digest does not match local metadata")
    # Only our own just-trained local artifact. A digest is NOT proof an untrusted pickle is safe.
    app.state.pipeline = joblib.load(path)
    app.state.metadata = metadata
    app.state.load_count = 1
    yield


app = FastAPI(title="Synthetic Pipeline Local Demo", lifespan=lifespan)


@app.exception_handler(RequestValidationError)
async def validation_error(request: Request, error: RequestValidationError):
    # Do not echo input/ctx: NaN/Infinity may be present and cannot be serialized as strict JSON.
    safe = [{"type": item["type"], "loc": list(item["loc"]), "msg": item["msg"]}
            for item in error.errors()]
    return JSONResponse(status_code=422, content={"detail": safe})


@app.get("/health")
def health():
    return {"ready": True, "model_version": app.state.metadata["model_version"],
        "feature_order": app.state.metadata["feature_order"],
        "artifact_sha256": app.state.metadata["artifact_sha256"],
        "model_load_count": app.state.load_count}


@app.post("/predict")
def predict(body: PredictInput):
    rows = np.asarray(body.rows, dtype=np.float64)
    try:
        # Some finite but extreme numbers can overflow preprocessing; do not turn that into500.
        with np.errstate(over="raise", invalid="raise", divide="raise"):
            classes = app.state.pipeline.predict(rows)
            probability = app.state.pipeline.predict_proba(rows)[:, 1]
        if not np.isfinite(probability).all():
            raise FloatingPointError("Nonfinite model output")
    except (ValueError, FloatingPointError, OverflowError) as error:
        raise HTTPException(status_code=422, detail={"code": "numerical_range",
            "message": "Feature magnitudes exceed this model's numerical range"}) from error
    return {"model_version": app.state.metadata["model_version"],
        "positive_class": 1, "predictions": [
            {"class": int(label), "probability_class_1": float(p)}
            for label, p in zip(classes, probability)]}
verify_http.py:
"""Train our artifact, run our own127.0.0.1 child, send real HTTP, terminate only that child."""
import hashlib
import json
import math
import socket
import subprocess
import sys
import time

import httpx
import joblib
import numpy as np

from train_model import ARTIFACTS, BASE, FEATURE_ORDER, MODEL_VERSION

HOST, PORT = "127.0.0.1", 8769


def main():
    train_run = subprocess.run([sys.executable, str(BASE / "train_model.py")],
                               capture_output=True, check=True)
    metadata = json.loads(train_run.stdout)
    fixture = json.loads((ARTIFACTS / "client_fixture.json").read_text())
    own_pipeline = joblib.load(ARTIFACTS / "pipeline.joblib")
    artifact_before = hashlib.sha256((ARTIFACTS / "pipeline.joblib").read_bytes()).hexdigest()
    # Refuse a busy port. Never discover/kill another process or reuse its server.
    with socket.socket() as sock:
        sock.bind((HOST, PORT))
    records = []
    proc = None
    shutdown = None
    log_path = BASE / "server-run.log"
    with log_path.open("w") as log, httpx.Client(base_url=f"http://{HOST}:{PORT}",
            timeout=5, trust_env=False) as client:
        try:
            proc = subprocess.Popen([sys.executable, "-m", "uvicorn", "api_app:app",
                "--host", HOST, "--port", str(PORT), "--log-level", "warning"],
                cwd=BASE, stdout=log, stderr=log)
            for _ in range(100):
                if proc.poll() is not None:
                    raise RuntimeError("Our server exited before readiness; inspect local server-run.log")
                try:
                    response = client.get("/health")
                    if response.status_code == 200:
                        ready = response.json()
                        assert ready["model_version"] == MODEL_VERSION
                        assert ready["artifact_sha256"] == artifact_before
                        break
                except httpx.TransportError:
                    pass
                time.sleep(.05)
            else:
                raise RuntimeError("Our server did not become ready")
            records.append({"case": "health_after_startup", "status": response.status_code, "body": ready})
            valid = [("single", {"rows": fixture["rows"][:1]}),
                ("batch3", {"rows": fixture["rows"]}),
                ("integer_numbers", {"rows": [[0, 1, -2, 3]]}),
                ("maximum_batch32", {"rows": [fixture["rows"][0]] * 32})]
            probability_errors = []
            for name, payload in valid:
                response = client.post("/predict", json=payload)
                assert response.status_code == 200, response.text
                body = response.json()
                x = np.asarray(payload["rows"], dtype=float)
                expected_class = own_pipeline.predict(x).tolist()
                expected_prob = own_pipeline.predict_proba(x)[:, 1]
                scale = own_pipeline.named_steps["scale"]
                classifier = own_pipeline.named_steps["classifier"]
                # Independent explicit transform + dot + sigmoid; do not use Pipeline.transform.
                z = (x - scale.mean_) / scale.scale_
                logits = z @ classifier.coef_[0] + classifier.intercept_[0]
                manual_prob = np.array([1 / (1 + math.exp(-float(v))) for v in logits])
                got = body["predictions"]
                assert [v["class"] for v in got] == expected_class
                error = max(abs(np.array([v["probability_class_1"] for v in got]) - manual_prob))
                probability_errors.append(float(error))
                assert np.allclose(expected_prob, manual_prob, atol=1e-14, rtol=0)
                assert error < 1e-14 and body["model_version"] == MODEL_VERSION
                records.append({"case": name, "status": response.status_code,
                    "request": payload, "body": body})
            invalid = [("empty_batch", {"rows": []}),
                ("too_many_rows", {"rows": [[0, 0, 0, 0]] * 33}),
                ("row3", {"rows": [[0, 0, 0]]}), ("row5", {"rows": [[0, 0, 0, 0, 0]]}),
                ("numeric_string", {"rows": [["1.0", 0, 0, 0]]}),
                ("bool", {"rows": [[True, 0, 0, 0]]}), ("null", {"rows": [[None, 0, 0, 0]]}),
                ("extra_field", {"rows": [[0, 0, 0, 0]], "debug": True}),
                ("missing_rows", {}), ("rows_not_matrix", {"rows": [0, 1, 2, 3]}),
                ("finite_but_overflowing_magnitude", {"rows": [[1e308, 1e308, 1e308, 1e308]]})]
            for name, payload in invalid:
                response = client.post("/predict", json=payload)
                assert response.status_code == 422, (name, response.text)
                assert response.headers["content-type"].startswith("application/json")
                records.append({"case": name, "status": response.status_code,
                    "request": payload, "body": response.json()})
            raw_cases = [("raw_NaN", '{"rows":[[NaN,0,0,0]]}'),
                ("raw_Infinity", '{"rows":[[Infinity,0,0,0]]}'),
                ("raw_negative_Infinity", '{"rows":[[-Infinity,0,0,0]]}'),
                ("exponent_overflow_1e400", '{"rows":[[1e400,0,0,0]]}'),
                ("malformed_json", '{"rows":')]
            for name, raw in raw_cases:
                response = client.post("/predict", content=raw, headers={"Content-Type": "application/json"})
                assert response.status_code == 422, (name, response.text)
                body = response.json()
                assert all(set(error) == {"type", "loc", "msg"} for error in body["detail"])
                records.append({"case": name, "status": response.status_code, "raw_request": raw, "body": body})
            response = client.get("/health")
            assert response.status_code == 200 and response.json()["model_load_count"] == 1
            records.append({"case": "health_after_all_requests", "status": 200, "body": response.json()})
        finally:
            if proc is not None:
                if proc.poll() is None:
                    proc.terminate()
                    try:
                        proc.wait(timeout=5)
                    except subprocess.TimeoutExpired:
                        proc.kill()
                        proc.wait(timeout=5)
                shutdown = {"owned_child_reaped": proc.poll() is not None,
                            "exit_code": proc.returncode, "host": HOST, "port": PORT}
    artifact_after = hashlib.sha256((ARTIFACTS / "pipeline.joblib").read_bytes()).hexdigest()
    assert artifact_before == artifact_after
    print(json.dumps({"scope": "Original localhost-only trained toy Pipeline API, actual HTTP, no public deployment",
        "metadata": metadata, "request_results": records,
        "checks": {"manual_pipeline_probability_max_error": max(probability_errors),
            "artifact_unchanged_by_requests": artifact_before == artifact_after,
            "model_load_count_after_requests": 1, "feature_order": FEATURE_ORDER,
            "probability_semantics": "class1 probability; not assurance the predicted class is calibrated",
            "validation_errors_do_not_echo_input_or_ctx": True},
        "server_shutdown": shutdown,
        "limits": ["Synthetic fixed split only, no CV/hyperparameter tuning or real-world model quality.",
            "All four values are positional according to metadata; numeric column swaps cannot be semantically detected.",
            "Strict input accepts JSON ints/floats, rejects strings/bools/null/nonfinite; finite numeric overflow gets422.",
            "NaN/Infinity tokens are nonstandard JSON; current parser accepts them before finite validation rejects them.",
            "Custom validation errors expose type/loc/msg only, preventing nonfinite input echo serialization failures.",
            "joblib loading only own trusted local artifact; matching digest alone does not make hostile pickle safe.",
            "Model/environment metadata is checked at startup; no arbitrary upload/load endpoint or request fit.",
            "No auth, public serving, TLS, concurrency/load test, monitoring, calibration or production deployment claim.",
            "Only the Popen child created here is terminated/reaped; no process discovery or unrelated termination."]}, indent=2, allow_nan=False))


if __name__ == "__main__":
    main()
可呼叫只是起點:下一個問題由誰負責?
到這裡,另一個程式已能依合約送資料,收到有版本與語意的結果,並在輸入錯誤時得到可處理的回應。Pipeline 保留相同的已 fit 前處理;API 把形狀、型別與回應協定放到明確邊界。
正式服務還會面對不同問題:誰能呼叫、如何限制資源、如何發現資料漂移、何時換模型、怎麼回滾與保留追溯紀錄。這份本機範例沒有實作 auth、TLS、監控、對外部署或負載測試,也沒有因為 HTTP 通了,就宣稱這些已完成。
先把眼前的邊界做好:模型究竟收什麼、前處理由誰 fit、回應是哪個類別的機率、失敗時是否仍是可讀的 JSON。這些問題的答案,才讓模型從一段只在作者環境理解的運算,變成其他程式能正確使用的一個功能。
來源與延伸閱讀:
-
scikit-learn Pipeline 與 train_test_split:前處理串接、fit/predict 與固定分割。查閱的 1.5 文件版本為 1.5.2,本文實跑為 1.5.1,沒有概括宣稱所有版本實作相同。
-
scikit-learn 模型保存:保存方法、環境相容與 pickle 類型載入的風險;本文只載入自家可信的固定檔案。
-
FastAPI Request Body 與 自訂 RequestValidationError:請求模型與錯誤處理。實跑版本與本次 raw HTTP 回應以完整程式/stdout 為準。
-
Pydantic 數值型別 與 額外欄位設定:strict、非有限值與額外欄位控制;本文數字範圍錯誤處理另在 API 內明寫。
-
圖 1:Displaying Pipelines 官方範例與 scikit-learn 1.5.2 BSD 授權。完整展示圖只表達結構;本文實跑版本仍為 1.5.1。
-
圖 2、3 的互動介面:Swagger UI 專案、Apache License 2.0,及保存聲明所對照的 v5.34.1 upstream NOTICE。截圖使用 CDN 的 @5 major alias,未保存當時所有載入資源 bytes,不能把後查的 5.34.1 當作確切擷取 patch。
-
支援本機應用的 FastAPI MIT 授權另附完整副本;這份 MIT 不被當成 Swagger UI 截圖的圖像授權。
圖像署名、改作與完整授權聲明:
DS69 image attributions and license texts

Figure 1 and cover: scikit-learn developers, official scikit-learn 1.5.2 documentation, “Displaying Pipelines”. Source: https://scikit-learn.org/1.5/auto_examples/miscellaneous/plot_pipeline_display.html . The graph is a documentation example showing Pipeline -> StandardScaler -> LogisticRegression; it is not the local fitted artifact. Image crop and proportional white-canvas cover fit are modifications. BSD 3-Clause license text follows.

Figures 2–3 and their mobile views: Sunny Data Science local synthetic API screenshots, captured from an isolated copy of the DS69 practice app. Swagger UI interface distributed under Apache License 2.0; full license text follows. FastAPI was used by the local application (MIT text included below for reference to the supporting project); the MIT license is not asserted as the screenshot's UI image grant. The screenshots were cropped to retain the request and actual response. The capture used FastAPI's default Swagger UI CDN major alias @5. The exact patch bytes were not pinned at capture time; the later package metadata reports 5.34.1 and is not a claim about the exact captured patch. The upstream swagger-ui-dist 5.34.1 distribution and matching official repository tag include the NOTICE reproduced below. This preserves the upstream attribution and does not identify the exact browser-loaded @5 patch.

scikit-learn BSD 3-Clause License (full text)
BSD 3-Clause License

Copyright (c) 2007-2024 The scikit-learn developers.
All rights reserved.

Redistribution and use in source and binary forms, with or without
modification, are permitted provided that the following conditions are met:

* Redistributions of source code must retain the above copyright notice, this
  list of conditions and the following disclaimer.

* Redistributions in binary form must reproduce the above copyright notice,
  this list of conditions and the following disclaimer in the documentation
  and/or other materials provided with the distribution.

* Neither the name of the copyright holder nor the names of its
  contributors may be used to endorse or promote products derived from
  this software without specific prior written permission.

THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS"
AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE
IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE
DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE
FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL
DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR
SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER
CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY,
OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.

Swagger UI Apache License 2.0 (full text)

                                 Apache License
                           Version 2.0, January 2004
                        http://www.apache.org/licenses/

   TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION

   1. Definitions.

      "License" shall mean the terms and conditions for use, reproduction,
      and distribution as defined by Sections 1 through 9 of this document.

      "Licensor" shall mean the copyright owner or entity authorized by
      the copyright owner that is granting the License.

      "Legal Entity" shall mean the union of the acting entity and all
      other entities that control, are controlled by, or are under common
      control with that entity. For the purposes of this definition,
      "control" means (i) the power, direct or indirect, to cause the
      direction or management of such entity, whether by contract or
      otherwise, or (ii) ownership of fifty percent (50%) or more of the
      outstanding shares, or (iii) beneficial ownership of such entity.

      "You" (or "Your") shall mean an individual or Legal Entity
      exercising permissions granted by this License.

      "Source" form shall mean the preferred form for making modifications,
      including but not limited to software source code, documentation
      source, and configuration files.

      "Object" form shall mean any form resulting from mechanical
      transformation or translation of a Source form, including but
      not limited to compiled object code, generated documentation,
      and conversions to other media types.

      "Work" shall mean the work of authorship, whether in Source or
      Object form, made available under the License, as indicated by a
      copyright notice that is included in or attached to the work
      (an example is provided in the Appendix below).

      "Derivative Works" shall mean any work, whether in Source or Object
      form, that is based on (or derived from) the Work and for which the
      editorial revisions, annotations, elaborations, or other modifications
      represent, as a whole, an original work of authorship. For the purposes
      of this License, Derivative Works shall not include works that remain
      separable from, or merely link (or bind by name) to the interfaces of,
      the Work and Derivative Works thereof.

      "Contribution" shall mean any work of authorship, including
      the original version of the Work and any modifications or additions
      to that Work or Derivative Works thereof, that is intentionally
      submitted to Licensor for inclusion in the Work by the copyright owner
      or by an individual or Legal Entity authorized to submit on behalf of
      the copyright owner. For the purposes of this definition, "submitted"
      means any form of electronic, verbal, or written communication sent
      to the Licensor or its representatives, including but not limited to
      communication on electronic mailing lists, source code control systems,
      and issue tracking systems that are managed by, or on behalf of, the
      Licensor for the purpose of discussing and improving the Work, but
      excluding communication that is conspicuously marked or otherwise
      designated in writing by the copyright owner as "Not a Contribution."

      "Contributor" shall mean Licensor and any individual or Legal Entity
      on behalf of whom a Contribution has been received by Licensor and
      subsequently incorporated within the Work.

   2. Grant of Copyright License. Subject to the terms and conditions of
      this License, each Contributor hereby grants to You a perpetual,
      worldwide, non-exclusive, no-charge, royalty-free, irrevocable
      copyright license to reproduce, prepare Derivative Works of,
      publicly display, publicly perform, sublicense, and distribute the
      Work and such Derivative Works in Source or Object form.

   3. Grant of Patent License. Subject to the terms and conditions of
      this License, each Contributor hereby grants to You a perpetual,
      worldwide, non-exclusive, no-charge, royalty-free, irrevocable
      (except as stated in this section) patent license to make, have made,
      use, offer to sell, sell, import, and otherwise transfer the Work,
      where such license applies only to those patent claims licensable
      by such Contributor that are necessarily infringed by their
      Contribution(s) alone or by combination of their Contribution(s)
      with the Work to which such Contribution(s) was submitted. If You
      institute patent litigation against any entity (including a
      cross-claim or counterclaim in a lawsuit) alleging that the Work
      or a Contribution incorporated within the Work constitutes direct
      or contributory patent infringement, then any patent licenses
      granted to You under this License for that Work shall terminate
      as of the date such litigation is filed.

   4. Redistribution. You may reproduce and distribute copies of the
      Work or Derivative Works thereof in any medium, with or without
      modifications, and in Source or Object form, provided that You
      meet the following conditions:

      (a) You must give any other recipients of the Work or
          Derivative Works a copy of this License; and

      (b) You must cause any modified files to carry prominent notices
          stating that You changed the files; and

      (c) You must retain, in the Source form of any Derivative Works
          that You distribute, all copyright, patent, trademark, and
          attribution notices from the Source form of the Work,
          excluding those notices that do not pertain to any part of
          the Derivative Works; and

      (d) If the Work includes a "NOTICE" text file as part of its
          distribution, then any Derivative Works that You distribute must
          include a readable copy of the attribution notices contained
          within such NOTICE file, excluding those notices that do not
          pertain to any part of the Derivative Works, in at least one
          of the following places: within a NOTICE text file distributed
          as part of the Derivative Works; within the Source form or
          documentation, if provided along with the Derivative Works; or,
          within a display generated by the Derivative Works, if and
          wherever such third-party notices normally appear. The contents
          of the NOTICE file are for informational purposes only and
          do not modify the License. You may add Your own attribution
          notices within Derivative Works that You distribute, alongside
          or as an addendum to the NOTICE text from the Work, provided
          that such additional attribution notices cannot be construed
          as modifying the License.

      You may add Your own copyright statement to Your modifications and
      may provide additional or different license terms and conditions
      for use, reproduction, or distribution of Your modifications, or
      for any such Derivative Works as a whole, provided Your use,
      reproduction, and distribution of the Work otherwise complies with
      the conditions stated in this License.

   5. Submission of Contributions. Unless You explicitly state otherwise,
      any Contribution intentionally submitted for inclusion in the Work
      by You to the Licensor shall be under the terms and conditions of
      this License, without any additional terms or conditions.
      Notwithstanding the above, nothing herein shall supersede or modify
      the terms of any separate license agreement you may have executed
      with Licensor regarding such Contributions.

   6. Trademarks. This License does not grant permission to use the trade
      names, trademarks, service marks, or product names of the Licensor,
      except as required for reasonable and customary use in describing the
      origin of the Work and reproducing the content of the NOTICE file.

   7. Disclaimer of Warranty. Unless required by applicable law or
      agreed to in writing, Licensor provides the Work (and each
      Contributor provides its Contributions) on an "AS IS" BASIS,
      WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
      implied, including, without limitation, any warranties or conditions
      of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
      PARTICULAR PURPOSE. You are solely responsible for determining the
      appropriateness of using or redistributing the Work and assume any
      risks associated with Your exercise of permissions under this License.

   8. Limitation of Liability. In no event and under no legal theory,
      whether in tort (including negligence), contract, or otherwise,
      unless required by applicable law (such as deliberate and grossly
      negligent acts) or agreed to in writing, shall any Contributor be
      liable to You for damages, including any direct, indirect, special,
      incidental, or consequential damages of any character arising as a
      result of this License or out of the use or inability to use the
      Work (including but not limited to damages for loss of goodwill,
      work stoppage, computer failure or malfunction, or any and all
      other commercial damages or losses), even if such Contributor
      has been advised of the possibility of such damages.

   9. Accepting Warranty or Additional Liability. While redistributing
      the Work or Derivative Works thereof, You may choose to offer,
      and charge a fee for, acceptance of support, warranty, indemnity,
      or other liability obligations and/or rights consistent with this
      License. However, in accepting such obligations, You may act only
      on Your own behalf and on Your sole responsibility, not on behalf
      of any other Contributor, and only if You agree to indemnify,
      defend, and hold each Contributor harmless for any liability
      incurred by, or claims asserted against, such Contributor by reason
      of your accepting any such warranty or additional liability.

   END OF TERMS AND CONDITIONS

   APPENDIX: How to apply the Apache License to your work.

      To apply the Apache License to your work, attach the following
      boilerplate notice, with the fields enclosed by brackets "[]"
      replaced with your own identifying information. (Don't include
      the brackets!)  The text should be enclosed in the appropriate
      comment syntax for the file format. We also recommend that a
      file or class name and description of purpose be included on the
      same "printed page" as the copyright notice for easier
      identification within third-party archives.

   Copyright [yyyy] [name of copyright owner]

   Licensed under the Apache License, Version 2.0 (the "License");
   you may not use this file except in compliance with the License.
   You may obtain a copy of the License at

       http://www.apache.org/licenses/LICENSE-2.0

   Unless required by applicable law or agreed to in writing, software
   distributed under the License is distributed on an "AS IS" BASIS,
   WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
   See the License for the specific language governing permissions and
   limitations under the License.

FastAPI MIT License (supporting project copy)
The MIT License (MIT)

Copyright (c) 2018 Sebastián Ramírez

Permission is hereby granted, free of charge, to any person obtaining a copy
of this software and associated documentation files (the "Software"), to deal
in the Software without restriction, including without limitation the rights
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
copies of the Software, and to permit persons to whom the Software is
furnished to do so, subject to the following conditions:

The above copyright notice and this permission notice shall be included in
all copies or substantial portions of the Software.

THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN
THE SOFTWARE.

Swagger UI upstream NOTICE (verbatim from official swagger-ui-dist 5.34.1 package and matching tag)
swagger-ui
Copyright 2020-2021 SmartBear Software Inc.
留言0
登入後就能留言。
登入